Back to Home
Back to Logs

Prediction of Chronic Kidney Disease By Boosting Classifiers
Posted on April 26, 2021
Topics:
Machine Learning
AI
Data Science
Research
Original post is here.
Data mining is a branch of Artificial Intelligence that is widely used to derive interesting patterns from a large volume of medical data. By making some mathematical approaches, data mining models extract patterns from data and later these patterns are used for the survival of patients.
Chronic Kidney Disease (CKD) is one of the deadliest diseases that slowly damages the human kidney. The disease remains undetected in its early stage and the patients can only realize the severity of the disease when it gets advanced. Hence, detecting such a disease at an earlier stage is a key challenge now.
So here is the thing, in this article, I am going to analyze the dataset and the performance of boosting algorithms for detecting Chronic Kidney Disease.
In addition to that, I will also discuss some key terms of Machine Learning and introduce a data mining tool, Weka.
➡️ Boosting Classifiers
Boosting algorithms or classifiers are easy to implement and proved to be better in previous medical researches. Boosting algorithm is an ensemble type machine learning algorithm which converts weak classifiers to strong model to achieve better accuracy. Boosting algorithms solved various healthcare problems such as prediction of protein structure class, cancer classification, and recognition of breast cancer. In this experiment, two popular boosting classifiers, AdaBoost and LogitBoost will be talked about.
➡️ DATASET
The dataset that I am going to use, contains information of 2800 patients where the number of healthy patients is 1050 and 1750 adults have Chronic Kidney Disease.
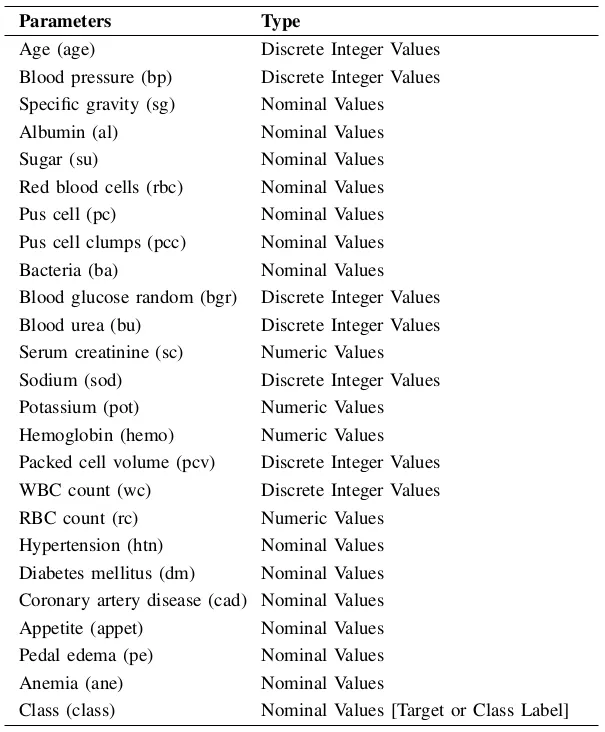
Table 1. The types of the attributes
Table 2. Details Analysis of Numerical Attributes
24 records such as age, blood pressure, sugar, blood urea, appetite, red blood cells, sodium, diabetes mellitus, etc. have been collected from each patient. Among them, 13 are categorical and 11 are numerical. Table 1 describes the types of attributes. Table 2 shows the descriptive analysis of numerical attributes of the CKD dataset.
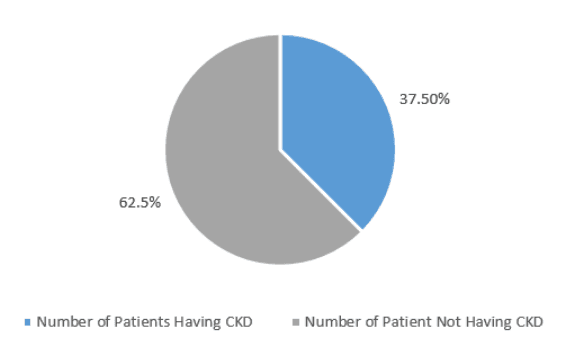
Fig. 1. Percentage of Healthy and Unhealthy Patients
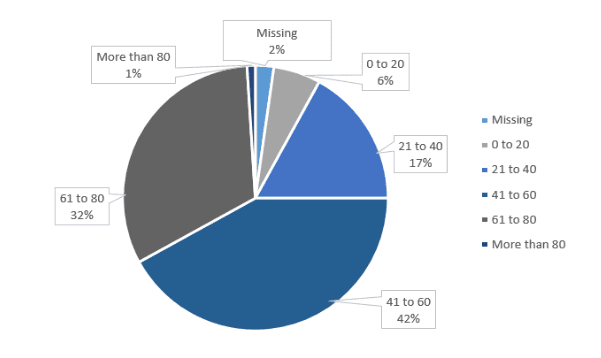
Fig. 2. Age Analysis of People in Dataset
There are two class labels (Figure 1). Among 2800, most people are from the age group 40 to 60 (Figure 2).
You will see two steps in this article-
- Applying AdaBoost and LogitBoost
- Analysis of their comparative results
But I will mostly focus on the result analysis. Before the above steps, we have to do some preprocessing to the model. Because the dataset contains missing values. As column values are repeated, therefore, missing values can be replaced by the mode values of that particular column. You may apply other preprocessing techniques to get more accurate high performance if you want. But for the time being, I will replace repeated values with mode value.
➡️ Applying AdaBoost and LogitBoost
I am a lazy developer. I don’t like to write code always. So when I save some time from coding, I take a nap. The same thing happens here. Instead of writing a bunch of python code, I have used WEKA 3.8 tool to apply the AdaBoost and LogitBoost. Weka is a tool for data mining tasks. Believe me, it's gonna save your time a lot. You may watch Netflix more or take a nap like me, haha! Hey, but I am not demotivating you to write code.
Weka
It is a visualization tool that contains algorithms for data analysis. It provides tools for data pre-processing, classification, regression, clustering, association rules, and visualization. You can find the tutorials for Weka here and here. And you can download Weka from here.
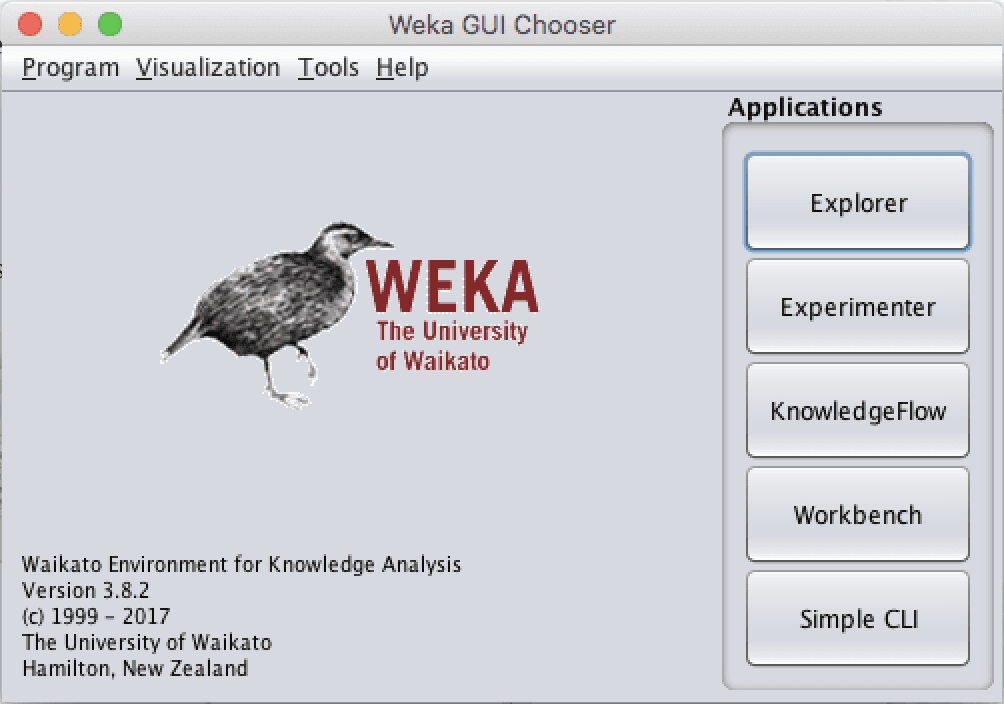
Weka GUI
I have a plan to write more details on Weka in near future.
➡️ Result Analysis
Accuracy Comparison
Accuracy is the common measurement for comparison among machine learning algorithms. Accuracy is calculated by summation of true positive and true negative divided by total instances (Equation 1).
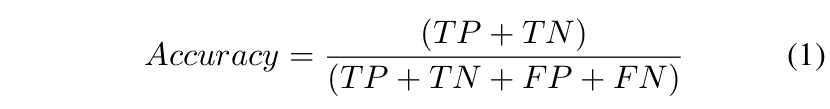
Let’s talk about TP, TN, FP, and FN a bit.
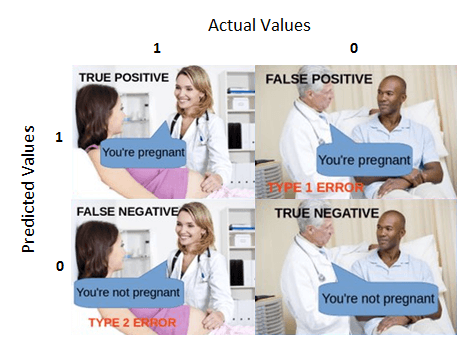
True Positive: You predicted positive and it’s true. You predicted that a woman is pregnant and she actually is.
True Negative: You predicted negative and it’s true. You predicted that a man is not pregnant and he actually is not.
False Positive: You predicted positive and it’s false. You predicted that a man is pregnant but he actually is not.
False Negative: You predicted negative and it’s false. You predicted that a woman is not pregnant but she actually is.
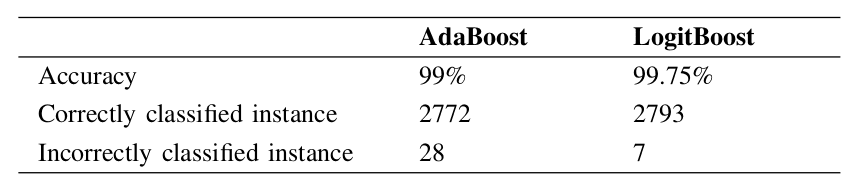
Table 3. Performance Analysis of AdaBoost AND LogitBoost
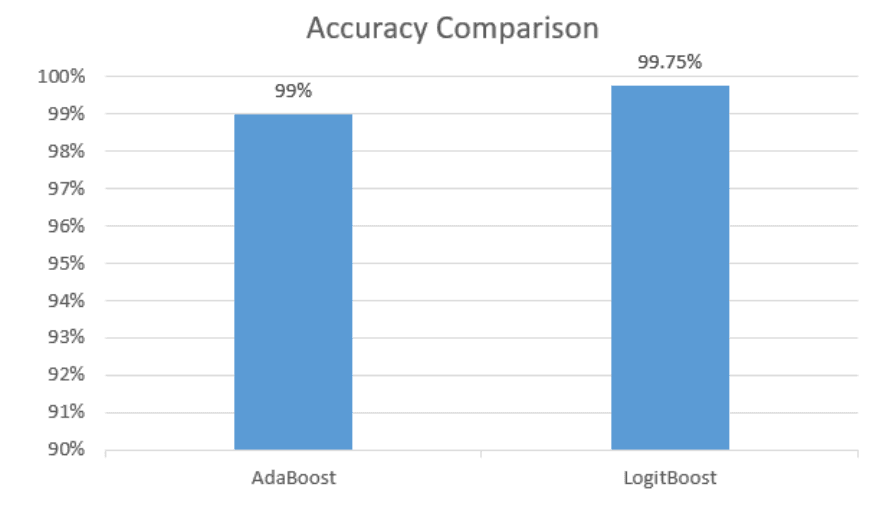
Figure 3. Accuracy Comparison of AdaBoost and LogitBoost
Both boosting algorithms AdaBoost and LogitBoost performed very well and
achieved good accuracy against the CKD dataset. Because as I said before boosting algorithms iteratively do the classification until it achieves better accuracy. Performance comparison between AdaBoost and LogitBoost based on Accuracy is shown in Table 3 and Figure 3.
Comparison of RMSE, F-Measure, and KAPPA Values
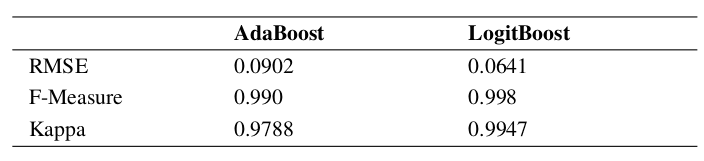
Table 4. Comparison of RMSE, F-Measure, and KAPPA Values
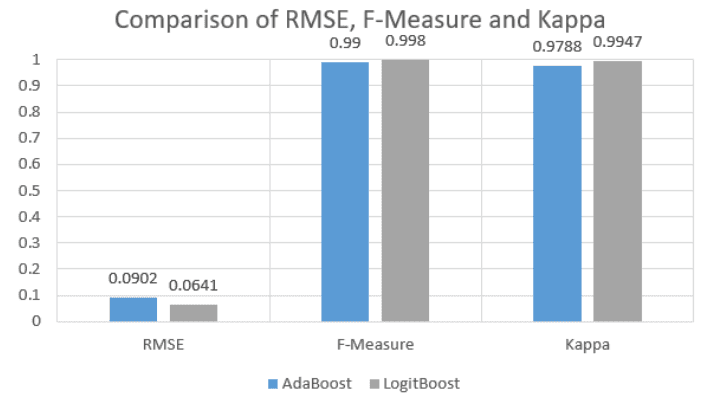
Figure 4. RMSE, F-Measure and Kappa Comparison Between AdaBoost and
LogitBoost
Root mean squared error interpretation: It tells the error between the actual result and predicted result. Equation 2 shows the formula of RMSE. It ranges from 0 to 1. As the low value of RMSE means a better fit model, the performance of AdaBoost was lower than LogitBoost’s performance (Figure 4).
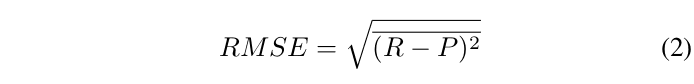
F-Measure interpretation: F-measure is a combined metric of precision and recall. Precision is defined as how many patients actually have CKD among all people who are thought to have CKD. Equation 3 describes the formula for calculating the f-measure. Recall refers to how many models can identify
among the patients who truly have CKD. Higher value of precision and recall is good. Table V contains precision and recall values which were resulted from applying AdaBoost and LogitBoost. It can be interpreted that LogitBoost performed well, as precision, recall and harmonic mean f-measure values
of LogitBoost are higher (Figure 4).
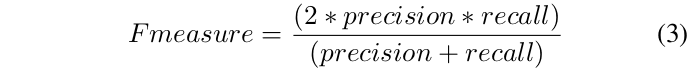
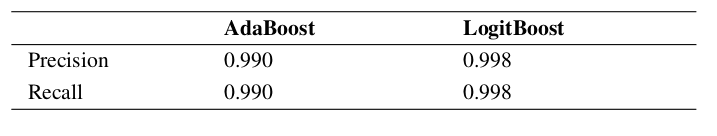
Figure 5. Values Precision and Recall of AdaBoost and LogitBoost
Kappa statistics interpretation: Value of Kappa ranges between 0 to 1 inclusive. When the Kappa value is above 0.75, that means there is a strong relationship between actual values and predicted values. Here, the Kappa value of LogitBoost is higher than the AdaBoost, which means predictions of LogitBoost are more accurate than the predictions of AdaBoost (Figure 5).
➡️ Final Observation
Both Boosting algorithms had an accuracy close to 100%, but we can come to a point that LogitBoost is the winner. As Logitboost is an updated version of Adaboost, it comes up with satisfactory results.
If you like this article, make sure to follow my Medium profile and check out other articles of mine!